> For the complete documentation index, see [llms.txt](https://help.bioinsight.illumina.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://help.bioinsight.illumina.com/illumina-trupath-genome/outputs-and-metrics/output-files-and-metrics.md).
# TruPath Outputs
This page describes key DRAGEN secondary analysis outputs and metrics.
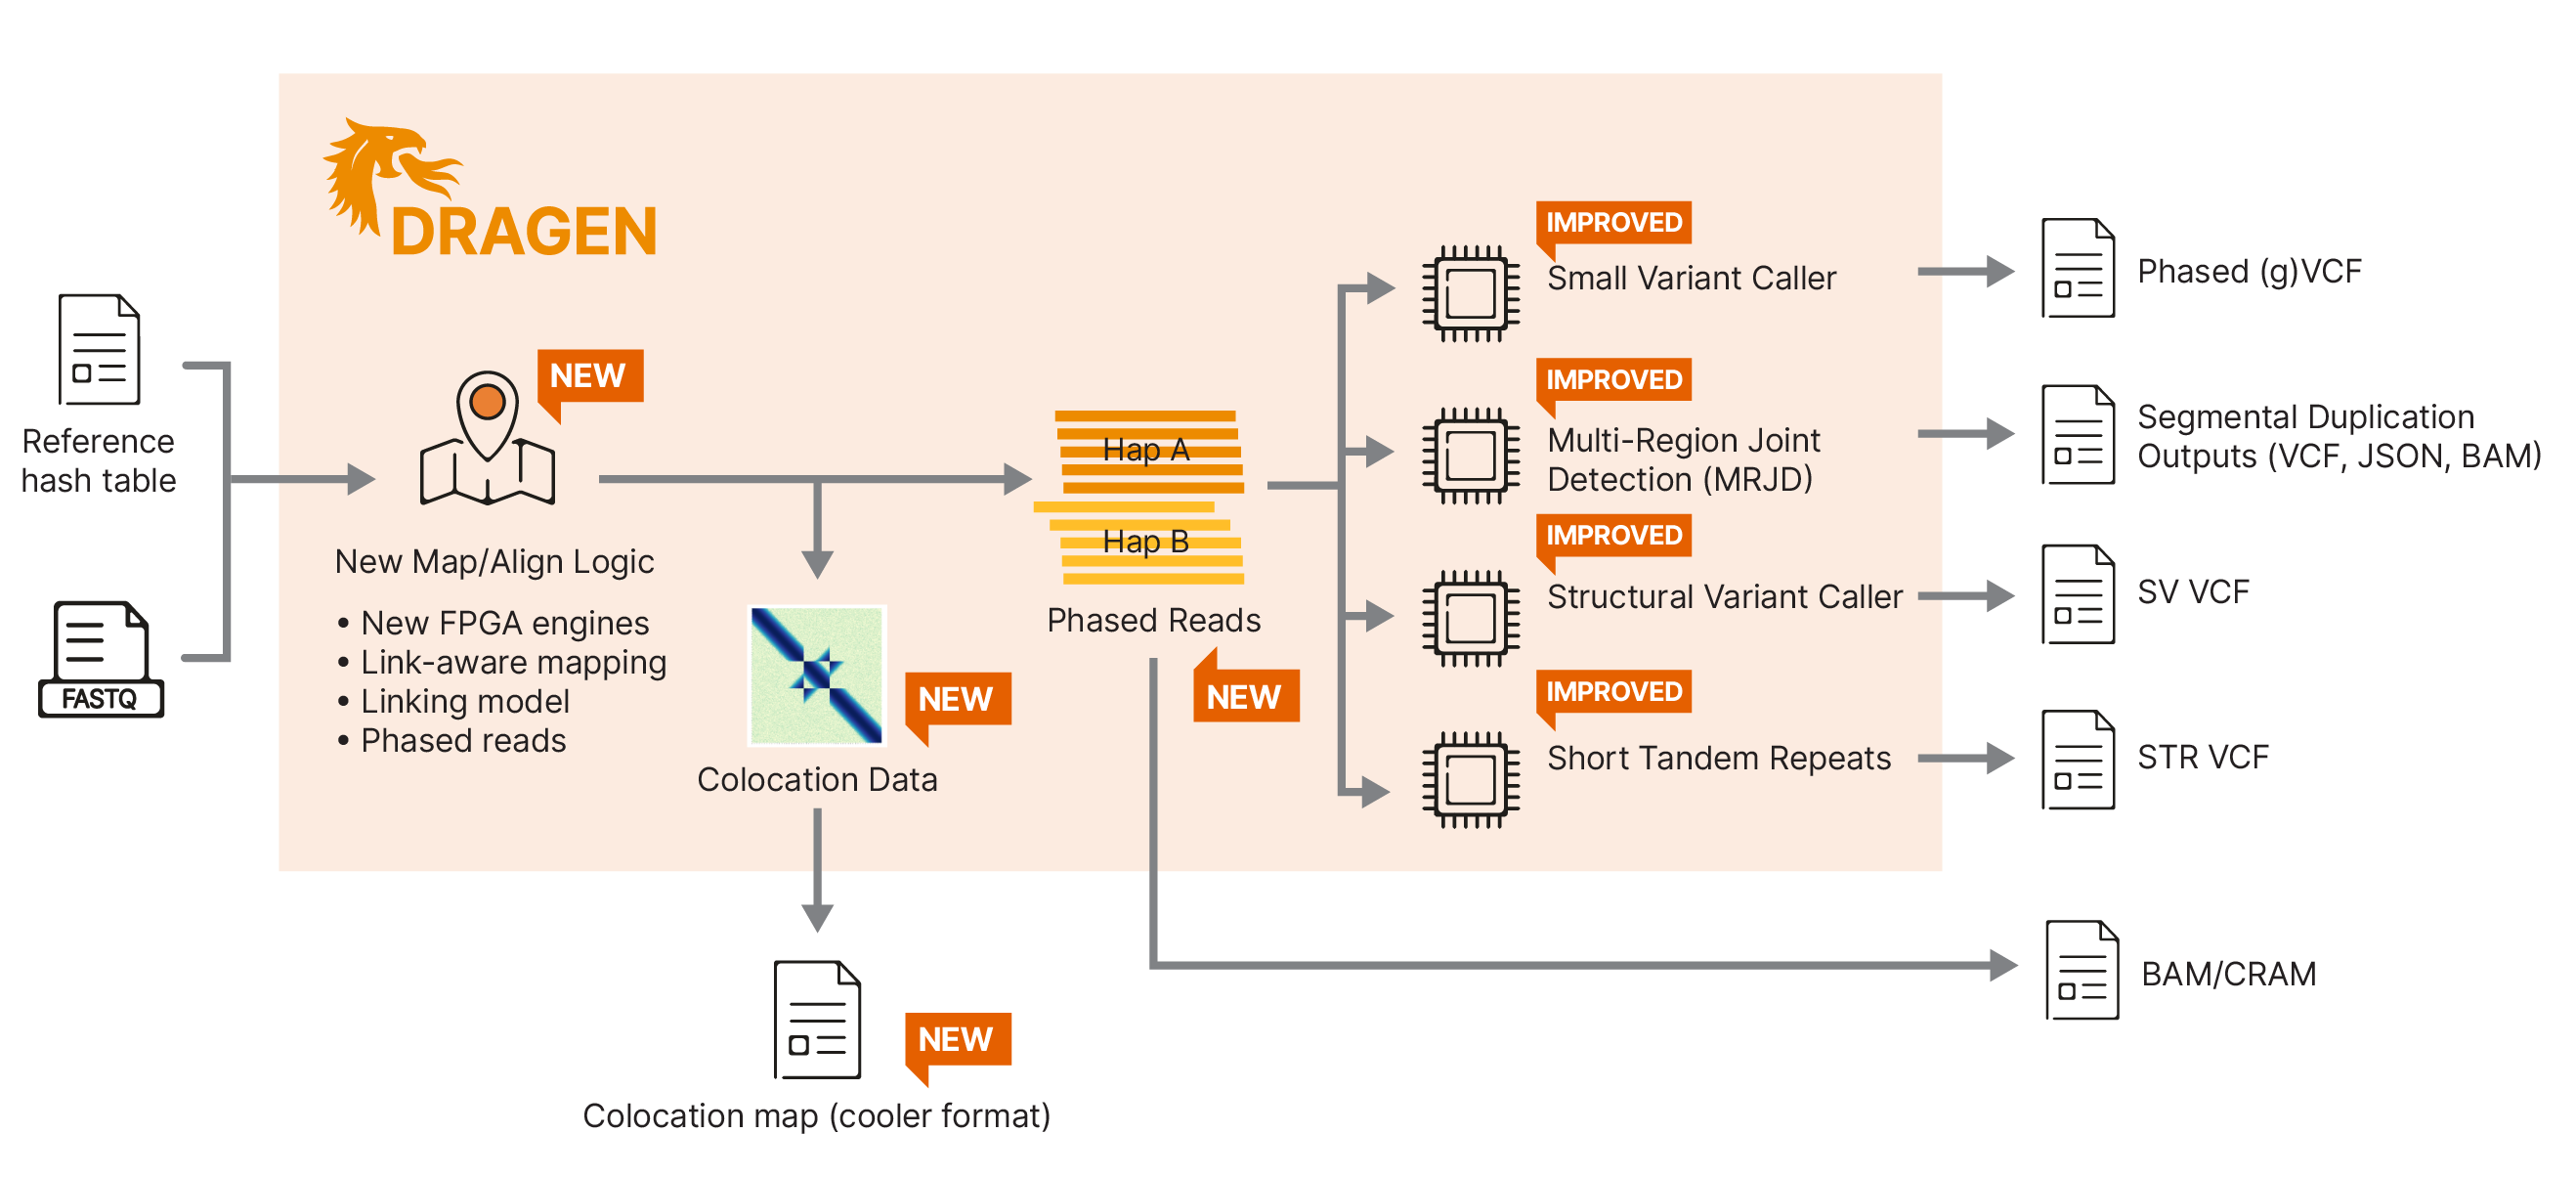
The proximity mode enabled DRAGEN Germline pipeline for use with the Illumina TruPath Genome prep produces a layered set of outputs that begin with **proximity‑aware templates and alignments,** expand into **long‑range phasing**, and culminate in **phased small variant calls, haplotype‑resolved SVs, small variants in paralogous regions (MRJD), STR expansion calls, and colocation‑validated break ends,** all backed by extensive QC and reporting. Each algorithm consumes the same underlying proximity signal but exposes results through **standard genomics artifacts (BAM, VCF, CSV, JSON, Cooler)**, making the workflow powerful yet interoperable.
For more information on the DRAGEN algorithms, features, and outputs supporting Illumina TruPath Genome prep, please navigate to the [DRAGEN User Guide linked here.](https://help.dragen.illumina.com/dragen-v4.5-trupath)
#### 1. Proximity Linking Model & Template Reconstruction
* A **non‑linear proximity linking model** is fit per read group using flow cell (X,Y) distance and genomic distance to reconstruct long DNA templates. This is the foundational signal reused by each downstream algorithm.
* Key Output Files:
* **Proximity‑aware BAM/CRAM**
* Reads tagged with **`BX:Z`** (template ID)
* **Template metrics CSVs** (WGS + QC regions):
* `._template_subpairs.csv`
* `._template_gdist.csv`
* `._template_xdist.csv`
* `._template_ydist.csv`
* `._template_thresholds.csv`
* **Link metrics CSVs**:
* `._proximity_gdist.csv`
* `._proximity_xdist.csv`
* `._proximity_ydist.csv`
#### 2. Proximity-Aware Mapping & Alignment
* Uses proximity link probabilities as an additional alignment score to resolve ambiguous mappings that standard short-read alignment cannot resolve.
* Key Output Files:
* **Mapped BAM/CRAM**
* Improved placement in repeats/paralogs
* Carries proximity and template tags
#### 3. Read Phasing & Personalized Haplotypes
* Combines haplotype databases with long‑range proximity links to create long, confident phase blocks, enabling haplotype‑aware variant calling and downstream analyses.
* Key Output Files:
* **Phased BAM/CRAM**
* Tags: `HP` (haplotype), `PS` (phase block), `pp` (phasing confidence)
* **Personalized haplotypes TSV**
* `.personal_haplotypes.tsv.gz`
* **Phase block GTF**
* `.phase_blocks.gtf.gz`
* **Imputed variants VCF**
* `.personal.vcf.gz`
* **Phasing metrics CSV**
* `.phasing_summary_stats.csv`
#### 4. Proximity-Aware Structural Variant (SV) Calling
* Uses haplotype‑segregated assemblies and phasing‑aware machine learning (ML) models to improve SV detection and genotyping in single‑sample germline WGS. Proximity information enters indirectly through phasing.
* Key Output Files
* **SV VCF**
* Includes TruPath‑specific fields:
* `PHASEDASM`
* `ML_UPDATED`
* `MLQS`
* `ColocationSum` (when colocation filter applied)
#### 5. Multi-Region Joint Detection (MRJD)
* Performs *de novo*, haplotype‑resolved small‑variant calling in paralogous regions, estimating copy number and assigning variants to specific gene copies or haplotypes using proximity information
* Key output files
* **Primary MRJD VCF**
* `.mrjd.hard-filtered.vcf.gz`
* **MRJD JSON summary**
* `.mrjd.json`
* Copy number, region/haplotype assignments, run status
* **MRJD phased BAM**
* `.mrjd.phased.bam`
* Tags: `HP` (copy), `PC` (confidence), `PS`, `BX`
* **Supporting files directory**
* `mrjd_supporting_files/`
* Multi‑column VCFs per paralog set
* Reference region alignments SAM
#### 6. STR Calling with IRR Recovery
* Recovers otherwise unmapped in‑repeat reads using proximity, enabling more accurate sizing of large STR expansions and improving genotyping in heterozygous cases.
* Key Output Files
* **STR VCF** (standard DRAGEN‑STR format)
* **BAM/CRAM with IRR tags**
* `tr` tag encoding recovered repeat motif
#### 7. Colocation Analysis & Filtering
* Summarizes long‑range genomic interactions from proximity‑linked reads and uses that signal to validate or filter SV break ends lacking molecular support
* Key Output Files:
* **Cooler file**
* Sparse colocation matrix (Hi‑C‑like)
* **SV VCF annotations**
* `NORMALIZED_COLOC_SUM`
* `ColocationSum` filter (when applied)
#### 8. Proximity‑Filtered Coverage & Reporting
* Provides QC and interpretability for proximity data quality, template structure, and phasing performance, integrated into standard DRAGEN Report
* Key Output Files:
* **Proximity coverage CSVs** (per link‑quality threshold):
* `_proximity_linkqual_coverage_metrics.csv`
* `_proximity_linkqual_hist.csv`
* `_proximity_linkqual_fine_hist.csv`
* `_proximity_linkqual_overall_mean_cov.csv`
* `_proximity_linkqual_contig_mean_cov.csv`
#### 9. DRAGEN Reports (TruPath Germline WGS)
* Dedicated *Proximity* tab with QC metrics and visualizations. See the DRAGEN Reports section of the DRAGEN User guide for additional information:
* Key Metrics:
* `Fit RMSE` - An estimate of how different the estimated probabilities can be between the parametric and non-parametric models, on the phred scale
* `Q25 Proximity Rate` - Percentage of read-pairs with at least one neighbor above Q25, on the phred scale
* `Q25 Proximity Coverage` - Average alignment coverage over genome with link-quality ≥Q25, on the phred scale
* `P75 Template Size` - The size of linked template molecules at the 75th percentile
* `NG50` - The size of the smallest phasing block required to phase 50% of the genome
* Key Plots and Visualizations are [described in this section here.](/illumina-trupath-genome/data-visualizations-and-analysis/visualize-data-in-dragen-reports.md)
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://help.bioinsight.illumina.com/illumina-trupath-genome/outputs-and-metrics/output-files-and-metrics.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.