> For the complete documentation index, see [llms.txt](https://help.bioinsight.illumina.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://help.bioinsight.illumina.com/icm/analyses/analysis-functionality/task-menu/biological-interpretation/correlation-engine-bioset-correlation.md).

# Correlation Engine bioset correlation

## What is Correlation Engine bioset correlation?

While Correlation Engine (CE) meta-analysis answers "does my signature replicate across studies?", bioset correlation answers a complementary question: "which specific studies show the strongest pairwise concordance with my signature?". The output of this task produces granular, study-level evidence for your findings by computing pairwise correlation scores between the gene/protein signature and CE's 201K+ public biosets.

{% hint style="warning" %}
Connected Multiomics V1.3 uses the Disease atlas Biosets from CE. Future release versions will include additional public Biosets and private Bioset libraries.
{% endhint %}

## Performing the CE bioset correlation task

* Single-click any gene/protein signature from these types of result nodes: differential analysis results (feature lists), QTL hits, MOFA factor loadings, SNF cluster markers, WGCNA module genes, or manually curated gene lists
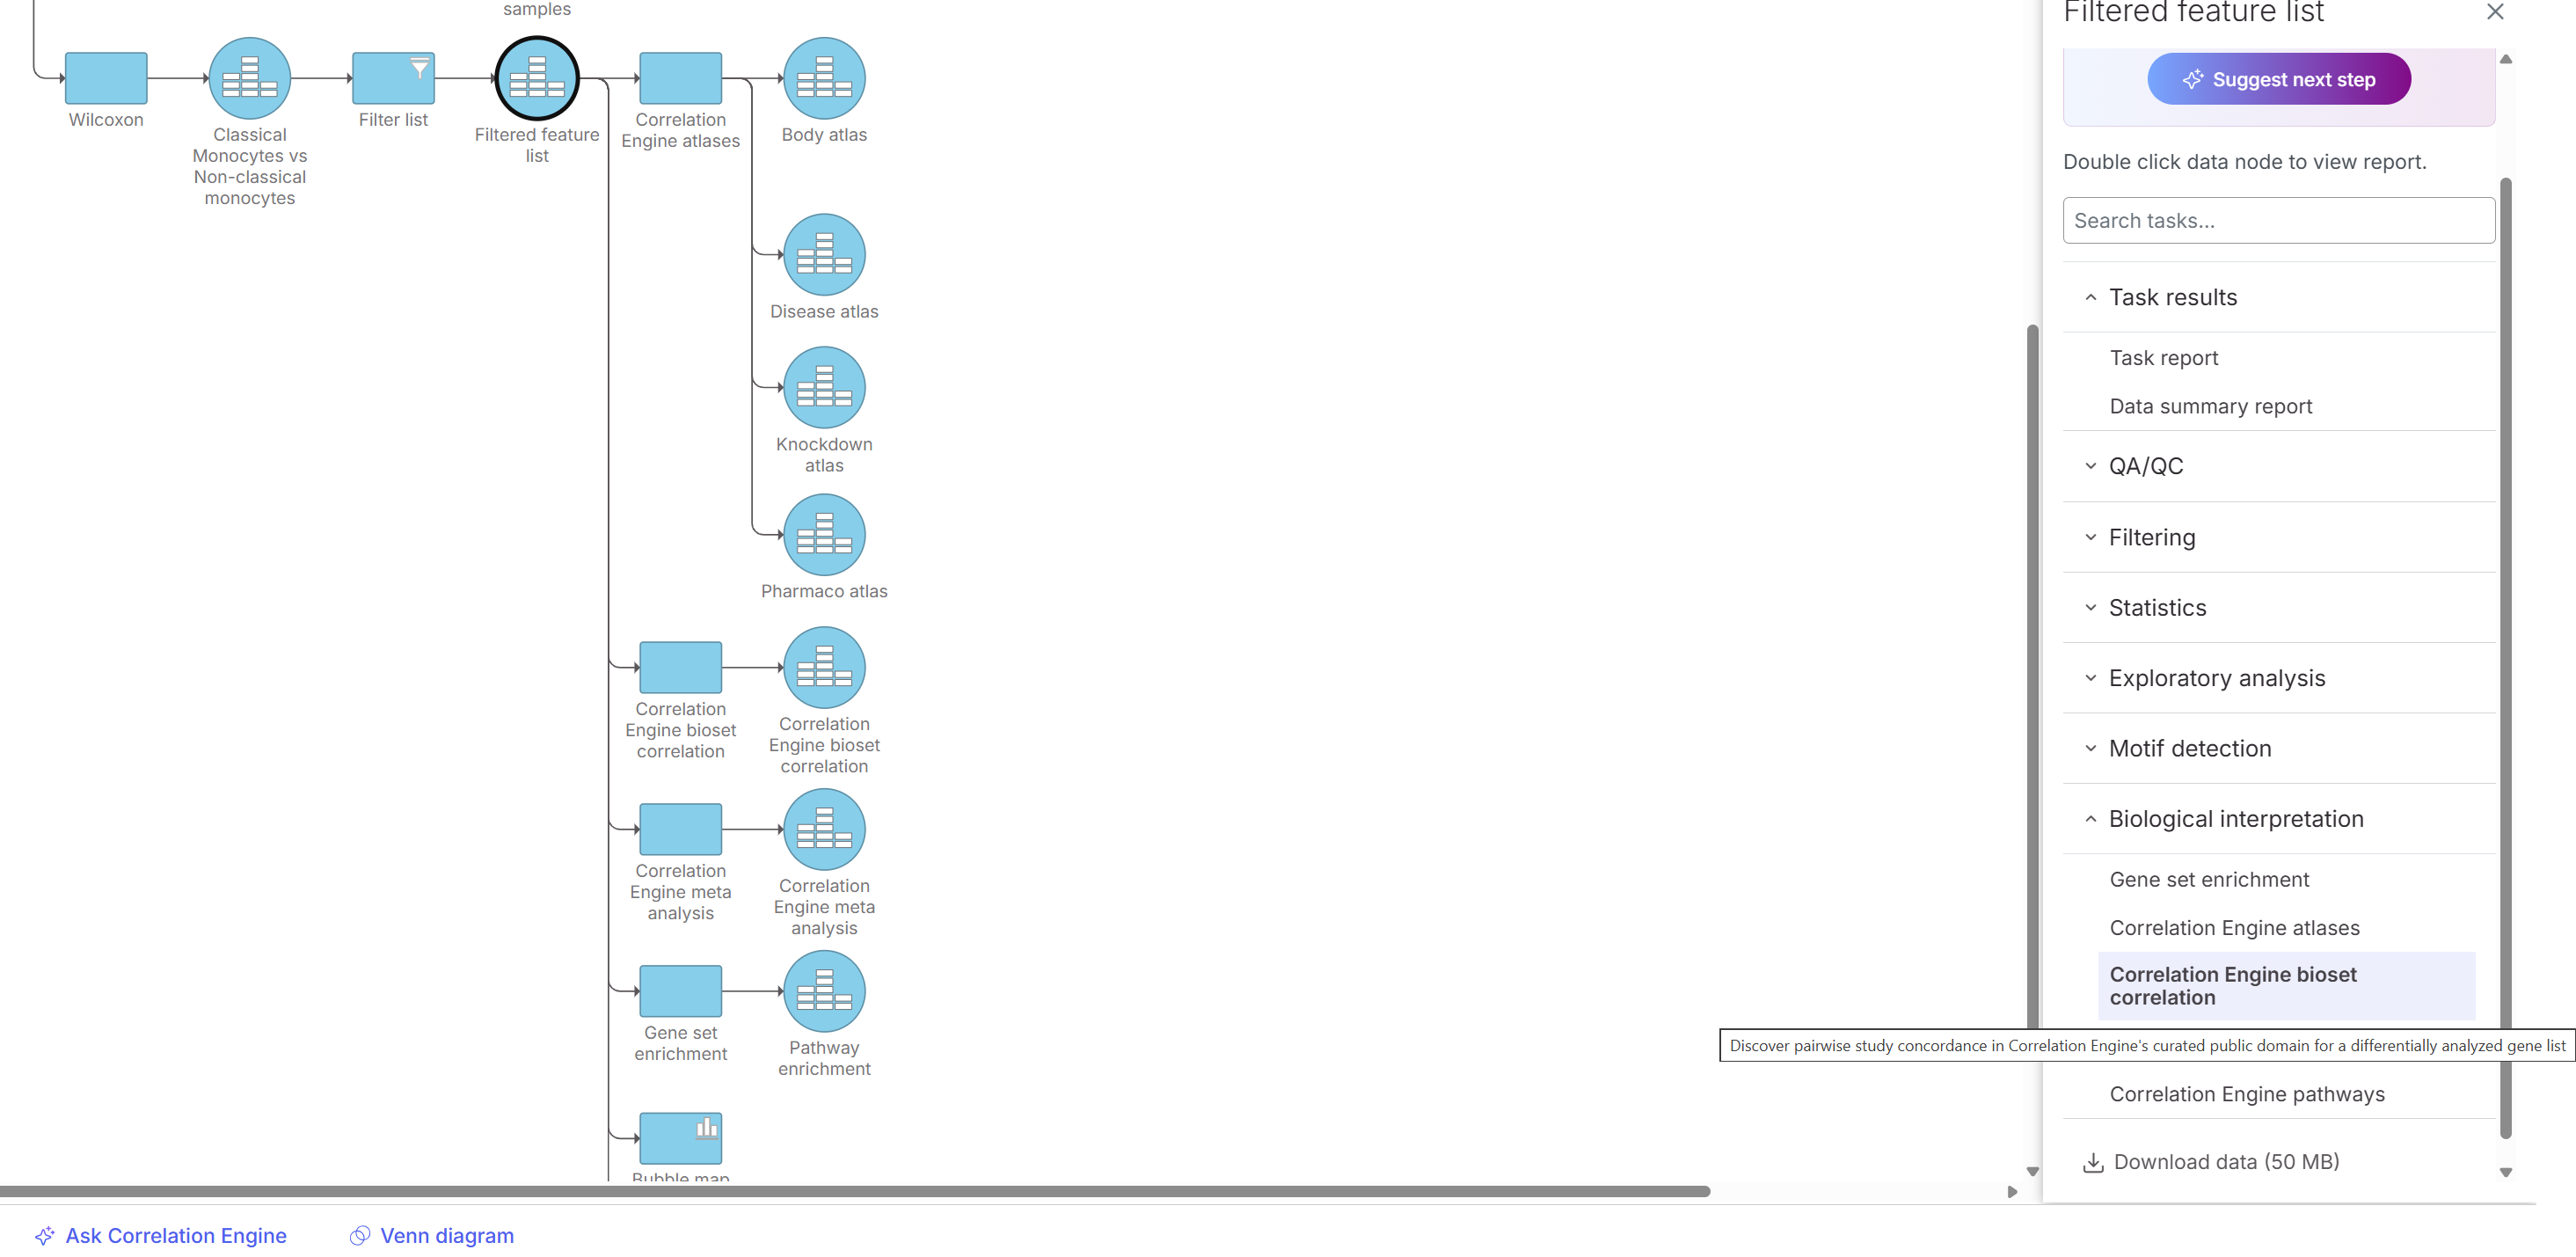
* In the context-sensitive toolbox select **Biological interpretation** > **Correlation Engine bioset correlation**

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-a1e84920e34fe78e9d146b457287946a7c1c4587%2Fimage%20(591).png?alt=media" alt=""><figcaption><p>Select the <strong>Correlation Engine bioset correlation</strong> task from the toolbox</p></figcaption></figure>

* Select the **Organism** using the drop-down or begin typing the name
* Select the **Correlation Engine project** or choose Other to enter a custom project name
* Enter a **Correlation Engine study name** that will be created for the analysis within the selected project
* Click **Next**

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-4c1c17c641394702de1fe6586e7e173fbd81b5c3%2Fimage%20(592).png?alt=media" alt=""><figcaption><p>Enter details for the task set up</p></figcaption></figure>

* **Select one or more contrasts** to use for Correlation Engine analysis. If multiple contrasts are selected, an analysis will be performed for each contrast and an enrichment table will be produced for each contrast
* **Select feature identifier** by choosing the column that contains the gene identifiers to use for the analysis
* Click **Next**

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-a332649a9664d3fa1784f9cf704392516df0bd14%2Fimage%20(593).png?alt=media" alt=""><figcaption><p>Bioset configuration for the task</p></figcaption></figure>

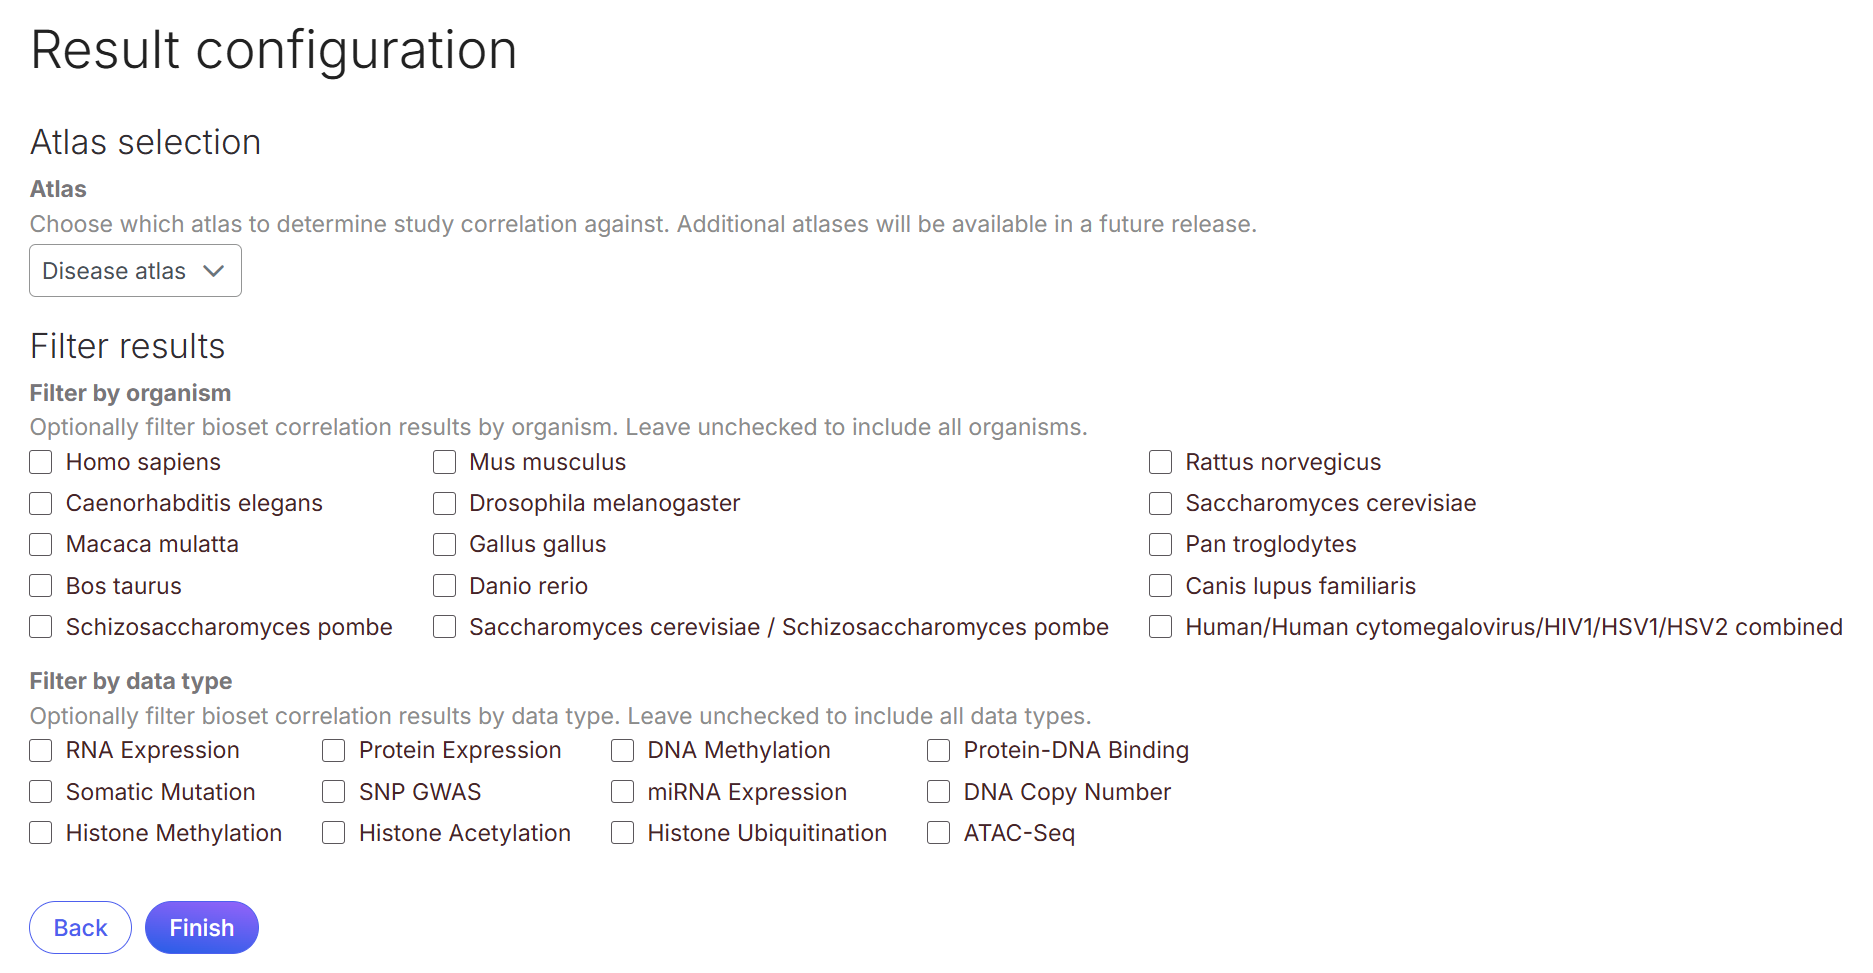
* Choose which atlas to determine study correlation against
* (Optional) Choose to filter the results by organism or data type
  * Leave **Filter by organism** and **Filter by data type** unchecked to include all organisms and data types in the results.
* Click **Finish**

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-15dda9b1b84cc97be22fcb33a3f0e4b61536cba7%2Fimage%20(594).png?alt=media" alt=""><figcaption><p>Result configuration for the task. Leave all filters unchecked to include all organisms and data types in the results</p></figcaption></figure>

The task produces a Correlation Engine meta analysis results node (circle).

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-06f8678272311433ace47c0437ebba119861eda4%2Fimage%20(595).png?alt=media" alt="" width="253"><figcaption><p>Correlation Engine bioset correlation results</p></figcaption></figure>

## Viewing the Correlation Engine bioset correlation results

* Double-click to open the Correlation Engine bioset correlation task report

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-7c5c29f6bacb6725bd484b7c2ccdd17462e290e4%2Fimage%20(596).png?alt=media" alt=""><figcaption><p>Correlation Engine bioset correlation report</p></figcaption></figure>

{% hint style="warning" %}
In the above image, study 4692148 shows up 3 times, because there are 3 biosets each with their own score against the query. There are some biosets from other studies that intermingle in the ranks. Study 4692148 get's a score = 100 because that is the best score of any of its biosets and that score is the best of all.
{% endhint %}

The table can be **downloaded** by clicking <img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-4acf74868c61c9b246e57a094c79c7ba47a01e0e%2Fimage%20(616).png?alt=media" alt="" data-size="line">.

The report list includes studies rank ordered by the strongest **Bioset score**. The columns can be **sorted** and **filtered** using text and operators such as >= or <= in the numeric columns.

Clicking a **Bioset ID** will take you to the Bioset in Correlation Engine and clicking a **Study ID** will take you to the study in CE.

Illumina has developed the *Running Fisher* algorithm for CE use. See more details in our technical note: [Data Correlation Details: Enrichment Analysis](https://www.illumina.com/content/dam/illumina-marketing/documents/products/technotes/technote-data-correlation-enrichment.pdf)

**P-value** is the bioset-bioset *Running Fisher* p-value

**Correlation direction** is the overall direction of the majority of genes as either positive/up or negative/down

The results can be viewed in the Data viewer by clicking <img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-cf4aacfe262cd61e6139343daa41259f3891cce2%2Fimage%20(570).png?alt=media" alt="" data-size="line">

<figure><img src="https://580316046-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FWMxqQAMFOJtu98OBk9KN%2Fuploads%2Fgit-blob-9749cf8288fe9e9e1d28cced3562d1c4590da0e9%2Fimage%20(597).png?alt=media" alt=""><figcaption><p>Task results shown in the Data viewer</p></figcaption></figure>


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://help.bioinsight.illumina.com/icm/analyses/analysis-functionality/task-menu/biological-interpretation/correlation-engine-bioset-correlation.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.