> For the complete documentation index, see [llms.txt](https://help.bioinsight.illumina.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://help.bioinsight.illumina.com/dragen-mirna/readme/read-structure.md).
# Read Structure
The Illumina miRNA Prep Kit is a single-end read solution that includes adapters and Unique Molecular Indices (UMIs). These UMIs tag each miRNA at an early stage, reducing PCR and sequencing bias.
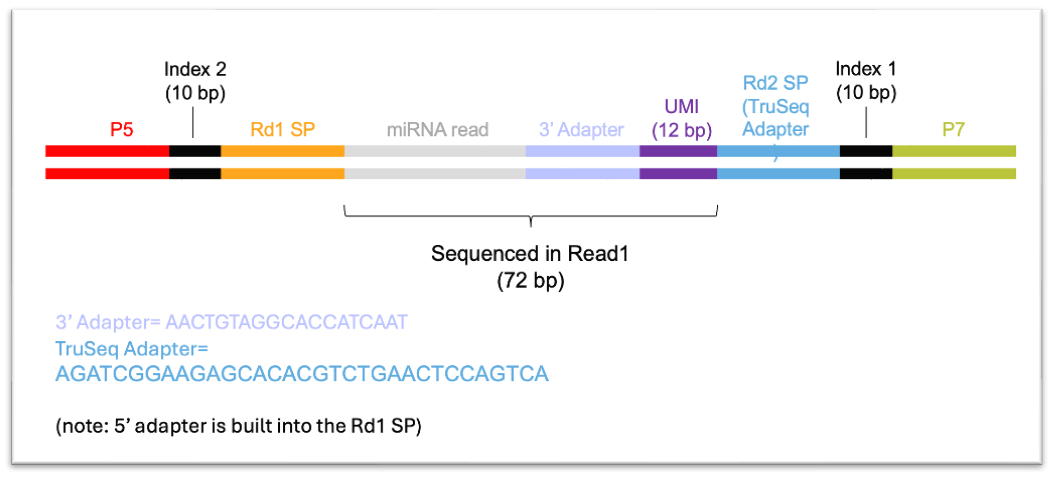
The 3′ adapter sequence (AACTGTAGGCACCATCAAT) is followed by the random UMI sequence, which is typically a 12 bp long random sequence. This is immediately followed by the TruSeq adapter sequence (AGATCGGAAGAGCACACGTCTGAACTCCAGTCA)
Figure 2. Read structure of Illumina miRNA prep reads.
The Truseq adapter sequence is removed at the demultiplexing stage (via BCLConvert) prior to secondary analysis.
The 3’ adapter sequence is removed at the secondary analysis step, after trimming, reads are classified accordingly:
* Reads are processed with cutadapt to remove 3′ UMI adapter and low-quality bases.
* Reads lacking 3’ UMI adapter sequence are separately tallied as no\_adapter\_reads.
* Insert and UMI identification After trimming, insert and UMI sequences are extracted. Reads with inserts shorter than 16 bp (too\_short\_reads) or UMIs shorter than 10 bp (UMI\_defective\_reads) are discarded
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://help.bioinsight.illumina.com/dragen-mirna/readme/read-structure.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.